About Me
I am an M.S. student in Computer Science at UC San Diego, advised by Prof. Hao Zhang in the Hao AI Lab, and I hold a B.S. from ShanghaiTech University advised by Prof. Kewei Tu. My research focuses on LLM inference infrastructure, GPU/TPU kernel optimization, sparse attention, and agents for performance engineering.
I am currently contributing to FastAFD, a new LLM inference engine that targets high-throughput workloads through Attention–FFN disaggregation. As a Student Researcher Intern at ByteDance Seed Infra, I worked on agentic TPU kernel optimization and high-performance inference kernels, and contributed to Seed’s internal vllm tpu-inference framework.
My work spans model architecture, on-chip dataflow, and serving systems: Flash-style GPU kernels for FlashMHF / FlashFFN, the official SGLang backend for HiLS-Attention, and training and inference infrastructure as one of the code owners of FastVideo.
Current Work
FastAFD
Ongoing contribution
Currently contributing to a new LLM inference engine that targets high-throughput workloads through Attention–FFN disaggregation.
AutoPallas & TPU Inference
Internal project
As code owner of AutoPallas, I developed an internal TPU kernel optimization agent with interactive task specification, configurable single-/multi-agent loops, parallel exploration, a strict correctness gate, and reusable optimization trajectories.
I also contributed to Seed’s internal vllm tpu-inference framework. My kernel work included optimizing Pallas paged attention through DMA pipelining and compute scheduling, reducing latency from 184.81μs to 117.16μs at 128K context. I used HLO/LLO analysis and XProf profiling, with XLA as a performance baseline.
Research & Open Source
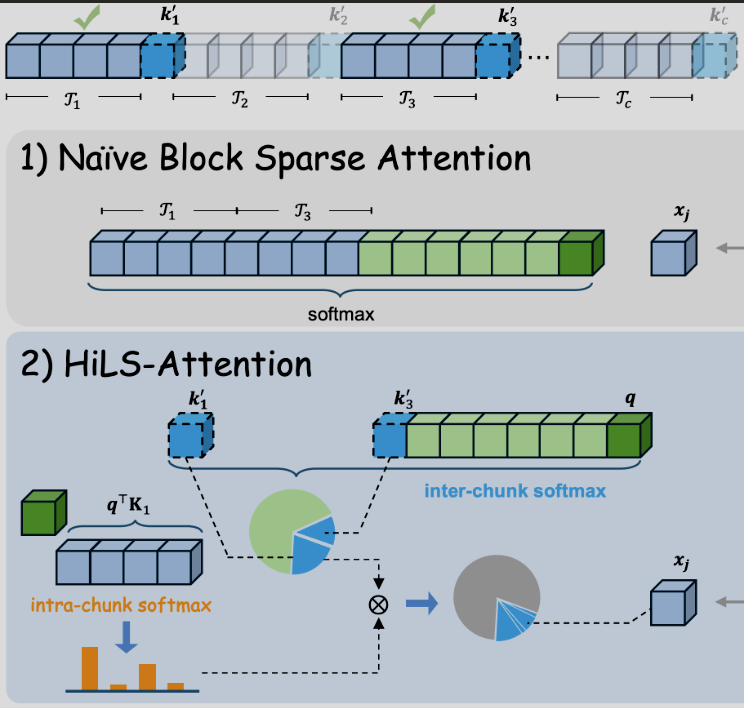
Hierarchical Sparse Attention Done Right
arXiv Preprint, Jul 2026
Built the official SGLang serving backend and reference inference system for learned chunk-wise sparse attention. Enables 512K-token serving and 64× context-length extrapolation, with up to 13.5× prefill and 15.7× decode speedup over dense attention at 512K context.
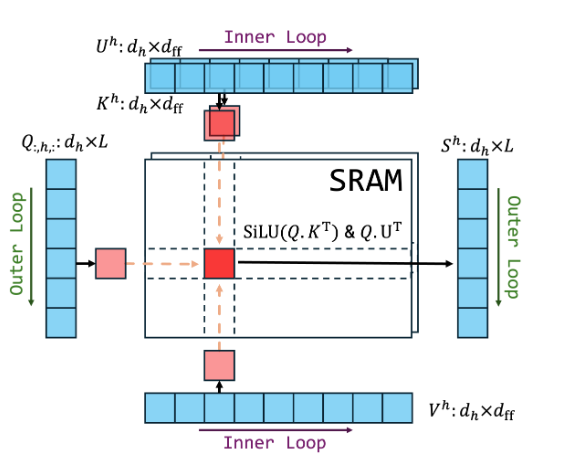
Flash Multi-Head Feed-Forward Network
arXiv Preprint, 2025
Software–hardware co-design for an efficient Transformer FFN architecture. Wrote Flash-style kernels in ThunderKittens/CUDA and Triton that keep intermediates in SRAM. FlashMHF reduces peak memory by 3–5× and achieves up to 1.08× inference speedup over the SwiGLU baseline while improving model quality.

FastVideo
Open-Source Project, Oct 2025 - Present
Training and inference infrastructure for video generation and world models. Contributed custom GPU kernels, inference optimization, and quantization-aware distillation, and helped develop the Blackwell-optimized DreamVerse runtime.
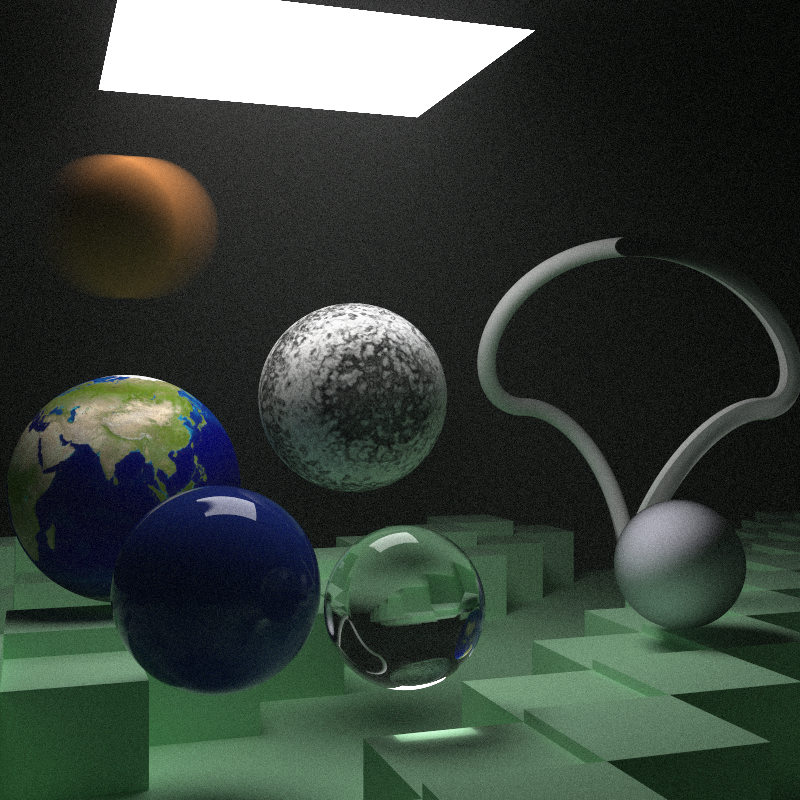
CUDA/C++ Parallel Image Rendering
Personal Project, 2023
Built a C++ path tracer supporting Lambertian, metal, dielectric, and emissive materials. Implemented motion blur, depth of field, and volumetric effects. Accelerated rendering via CUDA parallelization and importance sampling, achieving ~200× speedup vs. single-threaded CPU baseline.
Education

University of California, San Diego
Sep 2025 - Dec 2026 (Expected)Master of Science in Computer Science and Engineering
Teaching Assistant, CSE 291 / DSC 291: Machine Learning Systems
La Jolla, CA
University of California, Berkeley
Aug 2023 - Jan 2024Exchange Student, EECS Department
Berkeley, CA
ShanghaiTech University
Sep 2021 - Jun 2025Bachelor of Engineering in Computer Science and Technology
Shanghai, China